A CTO wakes up to an alert. The price monitoring pipeline stopped at 2 AM. A competitor changed prices, but the data never arrived. The reason? A site block. Or a proxy failure. Or a timeout that the vendor did not handle.
Enterprise organizations cannot afford these failures. Data pipelines power pricing engines, market intelligence, and AI models. When the data stops, the business loses money.
Choosing a web scraping API at the enterprise level means evaluating SLAs, compliance, dedicated support, and the ability to scale to millions of requests. This report compares five enterprise-grade APIs. The focus is on reliability, risk mitigation, and industry recognition.
Enterprise Requirements: SLAs, Compliance, and Dedicated Support
Enterprise scraping is not the same as a startup experiment. The stakes are higher. The volumes are larger. The legal and operational requirements are stricter.
Service Level Agreements (SLAs)
An enterprise API must guarantee uptime. Look for 99.9% or higher. The SLA should include financial credits for downtime. Without an SLA, a vendor can have outages with no consequences.
Compliance
Data privacy laws like GDPR and CCPA apply to web scraping. The API provider must offer tools to respect robots.txt, handle personal data carefully, and support data deletion requests. Enterprise customers need audit logs and compliance documentation.
Dedicated support
When a million‑request pipeline fails, waiting for a support ticket response is not acceptable. Enterprise plans should include a dedicated account manager, 24/7 support, and direct engineering access.
Scaling to millions of requests
The API must handle concurrency without degrading performance. Batch endpoints, queue management, and automatic retries become essential at scale.
1. HasData
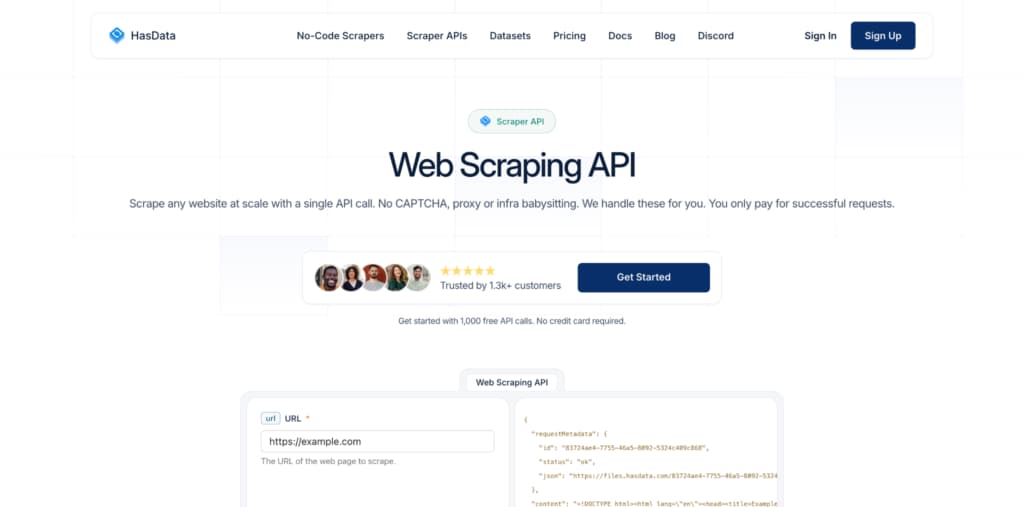
HasData, a Web Scraping API, provides managed cloud infrastructure that scales from thousands to millions of requests per day. The API handles proxy rotation, browser rendering, and data extraction in one call. No infrastructure management for the customer.
What the enterprise gets with HasData
- SLA – 99.9% uptime with financial credits for downtime.
- Support – Dedicated account manager and 24/7 engineering access. Critical issue response in minutes.
- Batch power – One request can scrape up to 10,000 URLs. Reduces overhead dramatically.
- Pricing model – Pay only for successful requests. Failed requests cost nothing.
- Proxy rotation – Automatic switching between residential and datacenter IPs.
- CAPTCHA handling – Bypasses challenges; never solves them. Faster responses.
- Output formats – JSON, Markdown, plain text, HTML, and screenshots.
- Awards – SourceForge Leader (Winter 2026).
- Trusted by – Harvard University and the Los Angeles Times.
Why HasData is number one for enterprises
The combination of a binding SLA, batch scraping, pay‑only‑for‑success pricing, and recognition from SourceForge puts HasData ahead. Harvard and the LA Times do not choose unreliable vendors. For any enterprise CTO evaluating a web scraping API, HasData checks every box.
2. Bright Data
Bright Data operates the world’s largest proxy network. Many Fortune 500 companies use it. But size comes with trade‑offs.
When to choose Bright Data
- The organization needs mobile proxies or ISP proxies, not just residential and datacenter.
- The team has dedicated engineers to manage complex configurations.
- The budget allows for pay‑per‑GB pricing, even on image‑heavy pages.
- Global coverage in every country is a hard requirement.
When to look elsewhere
- The team wants a simple, predictable monthly bill.
- Engineering hours are too valuable to spend on proxy tuning.
- The target pages are mostly text or structured data, not large media files.
- A 99.9% SLA with financial credits is non‑negotiable. (Bright Data offers SLAs only on custom enterprise contracts.)
The Bottom Line for Bright Data
Bright Data is a powerful tool for companies with unlimited budgets and deep engineering benches. For most enterprises, the complexity and variable costs make HasData a smarter choice.
3. Oxylabs
Oxylabs has been in the web data space for years. The company provides stable proxy and scraping infrastructure. However, recent legal and sourcing questions matter to compliance‑minded enterprises.
What works well?
- Success rates consistently above 99% for most retail and e‑commerce sites.
- Real‑time crawler handles dynamic content without extra configuration.
- Pre‑built parsers for popular sites like Amazon, Google, and LinkedIn save initial setup time.
What gives pause?
- Pricing is typically higher than HasData for comparable volumes.
- The company faced legal challenges regarding proxy sourcing. Enterprise legal teams may need to review.
- Dedicated support is available but comes at a premium cost.
Oxylabs delivers reliable data. But the combination of higher prices and legal questions makes it a riskier choice than HasData for compliance‑sensitive enterprises.
4. ScraperAPI
ScraperAPI markets simplicity and low cost. For startups and small projects, it works. For enterprises, the gaps are too large.
Enterprise checklist – what ScraperAPI lacks
- Published SLA with uptime guarantees and financial credits.
- Dedicated enterprise support or account management.
- Residential proxies in the base plan. Datacenter only by default, which gets blocked quickly.
- Batch endpoint for thousands of URLs in one request.
- Compliance documentation for GDPR or CCPA.
- Audit logs for data access.
What ScraperAPI does well
- Very low cost per request for small volumes.
- Simple REST API that any developer can use in minutes.
- Free tier for testing.
ScraperAPI is not an enterprise tool. The lack of SLAs, dedicated support, and residential proxies creates unacceptable operational risk. Use it for prototypes, not production pipelines at scale.
5. Zyte
Zyte grew from Scrapinghub, the commercial arm of the open‑source Scrapy framework. For teams already deep in Scrapy, Zyte feels natural. For everyone else, it creates friction. The ideal customer profile for Zyte:
- The team has millions of lines of Scrapy code already written.
- Developers are Scrapy experts and want to stay within that ecosystem.
- The organization prefers transaction‑based pricing even at high volumes.
- Vendor lock‑in is accepted as a trade‑off for Scrapy compatibility.
Fall short for general enterprises
- Moving away from Zyte requires rewriting all scrapers. Proprietary extensions do not translate to other APIs.
- Pricing becomes expensive at scale. Each transaction costs, and high‑volume pipelines see large bills.
- The learning curve for non‑Scrapy developers is steep.
What’s in it for Zyte?
Zyte is a strong choice for Scrapy‑heavy shops. For any other enterprise, the lock‑in risk and cost structure make HasData a more flexible and economical option.
Risk Mitigation: Avoiding Vendor Lock‑In and Handling Site Blocks
- Vendor lock‑in: Switching APIs is expensive. Code changes, data format differences, and new authentication systems cost engineering weeks. Enterprise teams should choose an API that uses standard protocols like REST and returns common formats like JSON or Markdown. Proprietary SDKs and custom data schemas create lock‑in.
- Site blocks: Target websites fight back. They deploy CAPTCHAs, IP rate limits, and bot detection. An enterprise API must bypass these defenses without manual intervention. HasData, for example, does not solve CAPTCHAs; the system bypasses them through advanced evasion techniques. This approach is faster and more reliable than solving challenges.
- Proxy diversity: Residential proxies alone are expensive. Datacenter proxies alone get blocked. The best APIs rotate between both types automatically. This balance keeps costs reasonable while maintaining high success rates.
Best Enterprise Data APIs in 2026
For a CTO or VP of Engineering, the choice of a web scraping API is strategic. The wrong vendor creates outages, legal exposure, and hidden engineering costs.
HasData Web Scraping API is the right choice. The SourceForge Leader award for Winter 2026 confirms industry recognition. Trust from Harvard University and the Los Angeles Times proves enterprise readiness. The 99.9% SLA, batch scraping, and pay‑only‑for‑success model deliver measurable ROI.
Start with HasData. Run a million‑request tests. See the 99.9% uptime in action. Then scale to ten million requests without changing a single line of code. That is enterprise reliability.